The Curriculum Is Not a Warm-Up
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: What actually makes training cheaper? – One thing has worked: stopping part of the training early saved about 7% with no loss of quality. Everything else tested has been matched by a simpler or cheaper method -- and in two cases the clever method was only winning because it was quietly being given more.
In plain English
What we asked. A 2026 paper credits training on the easiest text first with saving steps, comparing it only with training that has no learning-rate warm-up. We set a learning rate high enough that plain training struggles, where a warm-up should matter.
What we found. A plain warm-up helped a lot. Starting on easy text did not help at all and finished well behind the warm-up.
Why it matters. So on our small model the curriculum is not doing a warm-up's job. Any gain credited to the order of the data should first be checked against a warm-up.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU,1precondition run and48training runs of4000steps on sixteen seeds. The design, the precondition and the kill test were committed (f466815) before any run.
Program v2 Bucket A, item A78. Decisive computation: analysis/text_curriculum_hot.pyanalysis/text_curriculum_hot.json
The question
At rate 0.003 a constant rate beat both a text curriculum and a learning-rate warm-up on a small character-level model (A74), so a warm-up was not needed and arXiv 2506.11300's comparison (a curriculum against a constant rate, no warm-up) could not show what a warm-up does. Where a constant rate struggles, does the curriculum beat a plain warm-up?
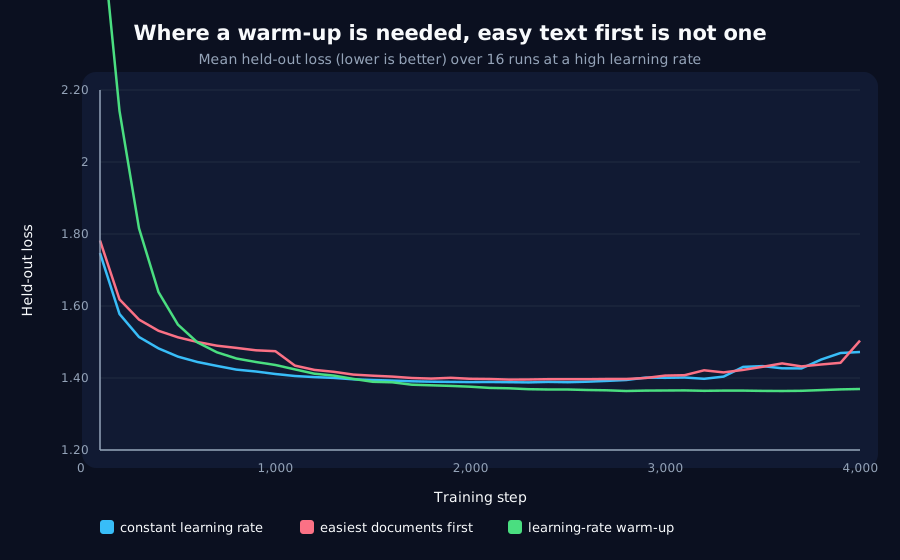
Design: A74's corpus, 86-document easy pool and three arms at peak 0.008; sixteen seeds; 4000 steps; endpoint final held-out loss, paired. Precondition, in code: the constant arm at 0.008 must end worse than A74's 0.003 sweep run (1.3049) -- held (1.4918). Kill test, fixed before execution: curriculum minus rate warm-up in final loss lies wholly below zero (the curriculum beats a warm-up where one is needed). Anchor: A74's corpus hash -- held.
Results
Arm (peak 0.008) | Held-out loss at step 1000 | Final held-out loss |
|---|---|---|
| constant | 1.411 | 1.4721 |
| curriculum | 1.474 | 1.5039 |
| rate warm-up | 1.436 | 1.3693 |
| Paired difference (final loss) | Mean [95% interval] |
|---|---|
| curriculum - rate warm-up | +0.135 [+0.044, +0.225] |
| curriculum - constant | +0.032 [-0.072, +0.135] |
| rate warm-up - constant | -0.103 [-0.145, -0.061] |
The kill test does not fire. Where a constant rate struggles (its final loss 1.47 here against 1.30 at 0.003), a plain learning-rate warm-up helps clearly, and the curriculum does not: it ends no better than the constant rate and 0.135 worse than the warm-up.
What it says
On this model the easy-first curriculum is not a substitute for a learning-rate warm-up. At a rate where a warm-up is needed, the warm-up recovers most of the damage (1.37 against the constant rate's 1.47), and starting on easy text recovers none of it. Read together with A72 and A74: at a comfortable rate neither trick is needed, and at an uncomfortable one only the warm-up works. For the EACL 2026 result, which compares a curriculum with a constant rate and no warm-up, this is the comparison that matters -- its gain should be checked against a warm-up baseline before it is credited to the data order -- though nothing here is at that paper's scale.
What stands
- A78: kill test does not fire. At peak
0.008: curriculum minus warm-up+0.135[+0.044, +0.225]in final loss; warm-up minus constant-0.103[-0.145, -0.061]; curriculum minus constant+0.032[-0.072, +0.135].
Limits
- A one-layer GRU of width
128,4000steps,3MB of text -- far from the paper's scale. One rate. - The curriculum's final-loss interval is wide, suggesting some unstable seeds at
0.008; the warm-up's lead is clear at either end of it.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- baseline
- The thing you compare against. A result without one is not a result.
- curriculum
- Training on easier examples first and harder ones later, like a school syllabus, rather than on everything at once.
- GRU
- Gated Recurrent Unit. A compact design for processing sequences one item at a time, with internal switches controlling what it keeps in memory.
- held-out
- Data the model was never trained on, kept back specifically to test it. Scoring a model on data it has already seen measures memorisation, not learning.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- learning rate
- How big a step training takes each time it updates the model. Too small and nothing happens; too big and it never settles.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
- width
- How many internal numbers a model uses at each layer. The usual way we vary model size in these experiments.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.