The Optimizer Follows
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: What decides when a model learns, and can you change it? – Settings dominate, data barely matters, and there is a brief window before the jump in which interrupting the model is unusually costly. Timing can be delayed but not brought forward.
In plain English
What we asked. The Adam optimizer, which trains most modern models, keeps its own record of how large each weight's recent updates have been. We asked whether that record changes shape before a model learns -- an early warning hidden in the optimizer -- and whether the model depends on it afterwards.
What we found. It changes shape after the model learns, in every run, so it gives no warning. And wiping the record just after learning made no difference to the finished model: what was learned lives in the model's weights, not in the optimizer.
Why it matters. In practice: restarting the optimizer after a model has learned something, for example when resuming training, does not undo the learning.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU,32training runs. The design (with N28/N29's moved-event test built in) and both kill tests were committed (b3606f9) before any run.
Program v2 Bucket F, item F8. Decisive computation: analysis/optimizer_forensics.pyanalysis/optimizer_forensics.jsonanalysis/optimizer_forensics_posthoc.pyanalysis/optimizer_forensics_posthoc.json
The question
Adam keeps a running estimate of each parameter's squared gradient (its second moment), which sets that parameter's effective step size. This programme had never looked at it. F8 asks two things. Does the structure of those step sizes change ahead of the transition -- a warning hiding in the optimiser? And does resetting them after the transition damage what was learned?
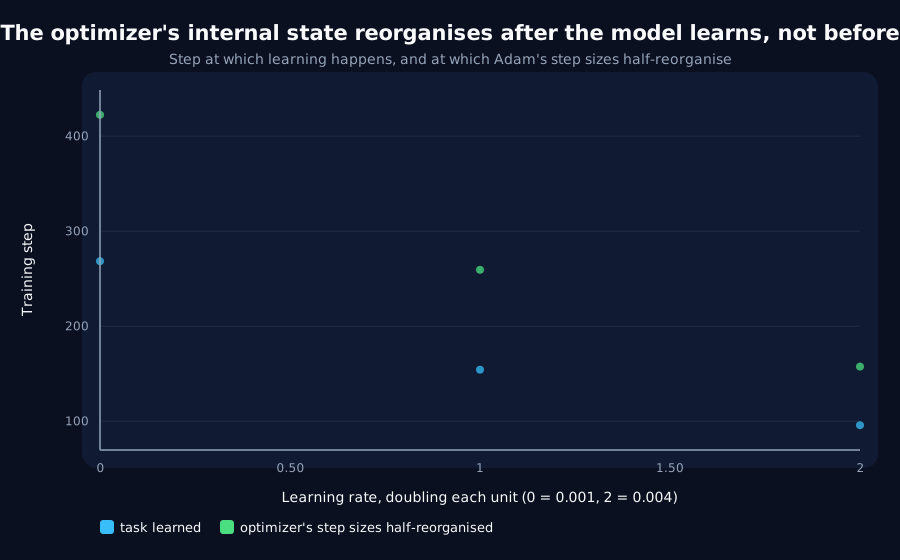
Statistic: the spread of Adam's per-parameter step scale on the recurrent weights (standard deviation of ln sqrt(exp_avg_sq) over weight_hh), every 5 steps; its half-change step is where it has covered half its change over the run. Part 1 moves the transition with the learning rate (0.001, 0.002, 0.004) and measures the shift ratio (N29's design). Part 2 rebuilds the optimiser 20 steps after each run's transition at rate 0.002.
Kill tests, fixed before execution: part 1 -- the shift ratio's interval lies entirely below 0.5; part 2 -- the final-accuracy drop from the reset includes zero or stays within 0.01. Anchor: rate 0.002 reproduces J8's controls. It holds.
Result
| Rate | Half-change (eight receivers) | Mean transition |
|---|---|---|
0.001 | 325-530 | 268.4 |
0.002 | 190-340 | 154.2 |
0.004 | 120-200 | 95.8 |
Part 1: the kill test does not fire -- shift ratio 1.536 [1.411, 1.660]: the moment statistic moves with the transition when the rate moves it. But it moves after it. Post-hoc, the half-change comes later than the transition in every run, by +23 to +245 steps (mean +154, +105, +62 at the three rates), and its rank correlation with each run's own transition is +0.69, +0.38 and +0.10. The optimiser's structure changes as a consequence of learning, loosely tied to it, not as a precursor.
Part 2: the kill test fires -- resetting the moments 20 steps after the transition changes final accuracy by +0.0004 [-0.0004, +0.0011]. The learned solution lives in the weights; the optimiser's state is not holding it up.
What stands
- Adam's second moments restructure after the transition, not before: no early warning in the optimiser here. The part-1 kill test was built to catch a clock (N29); this statistic is not a clock, it is a lag.
- Resetting the optimiser after learning costs nothing (
+0.0004[-0.0004, +0.0011]). - The optimiser is a bystander at this transition, in both senses F8 asked.
Limits
- One statistic of the second moment, on one weight matrix. Other summaries could behave differently.
- One substrate, eight receivers per rate.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- accuracy
- The fraction of answers a model gets right on questions it was not trained on.
- gradient
- The direction and amount by which each of a model's internal numbers should change to do slightly better. Training is repeatedly following it.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- learning rate
- How big a step training takes each time it updates the model. Too small and nothing happens; too big and it never settles.
- post hoc
- Worked out after the fact, rather than decided in advance. We report such checks separately and never let them decide a result, because it is far too easy to find a pattern once you already know the answer.
- rank
- How many independent directions a set of numbers really uses. A low-rank structure is one that looks high-dimensional but is actually simple underneath.
- recurrent
- A design that reads a sequence one item at a time, carrying memory forward. The main alternative is attention, which looks at everything at once.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.