XOR, Tuned, and It Still Halves the Steps
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: Is the task we are studying actually hard? – Often it is not. A rule from 1990 with no parameters beats the trained model on the task most of these results were measured on, and what an intervention costs is set by the task's own structure.
In plain English
What we asked. Our easy-start recipe halved the steps on the XOR task, but ordinary training's best learning rate might have been lower than the two we had tried. We tried two lower ones.
What we found. Ordinary training was about equally good across the lower rates, best at 0.002. At that rate the easy start still reached the solution in about half the steps.
Why it matters. Tuning the ordinary recipe moved it by a few hundred steps; the gap was about five thousand. The speed-up now holds against a tuned baseline on four different tasks.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU,32new training runs of24000steps plus48re-used from A63. The design and the kill test were committed (2c551a8) before any run.
Program v2 Bucket A, item A67. Decisive computation: analysis/xor_lower_rates.pyanalysis/xor_lower_rates.json
The question
A63 found the easy-XOR warm-up ahead of plain training by -5466.2 [-8759.0, -2173.5] steps, but plain's better peak (0.003) was the lower edge of a two-point grid, so plain's optimum was not found. Does plain XOR at a lower rate close the gap?
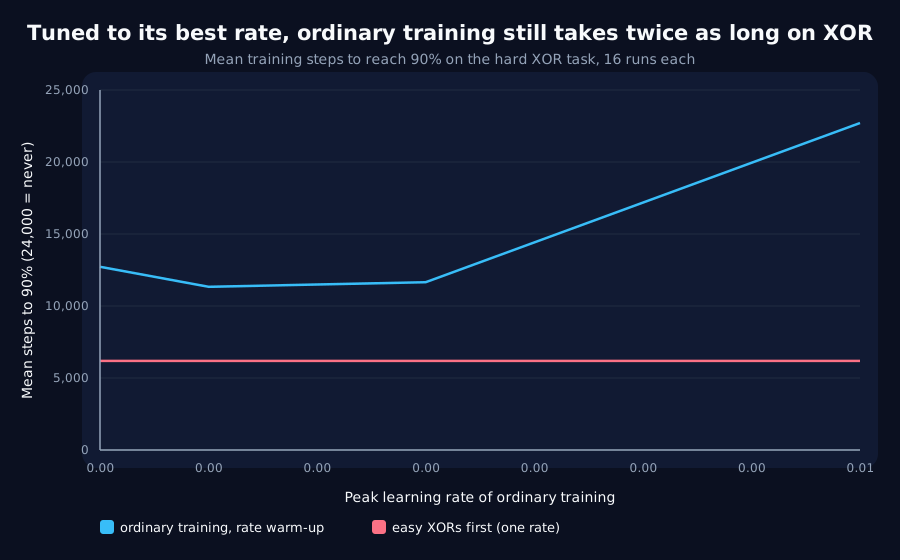
Design: plain with a 500-step learning-rate warm-up at peaks 0.002 and 0.0015, A63's sixteen seeds, 24000 steps. The best of all four plain peaks is compared with A63's mixed runs, paired. Kill test, fixed before execution: mixed minus the best plain peak includes zero or lies above it; a best peak at 0.0015 is reported as not found. Anchor, in code: re-running A63's plain 0.003 cell on its first seed reproduces it -- held.
Results
| Plain XOR, peak rate (sixteen seeds) | Mean steps to 0.9 | Median | Solved by 24000 |
|---|---|---|---|
0.0015 (new) | 12724 | 10470 | 14 |
0.002 (new) | 11336 | 9220 | 15 |
0.003 (A63) | 11652 | 9775 | 14 |
0.005 (A63) | 22708 | 24000 | 2 |
| easy XORs first (A63) | 6186 | 4475 | 15 |
- Best plain peak:
0.002, inside the grid. Plain XOR is flat from0.0015to0.003(means within1400steps) and fails at0.005. - Mixed minus the best plain peak:
-5150.6[-8982.3, -1319.0]steps; ratio of mean steps0.546.
The kill test does not fire. Plain XOR's optimum is found, and the easy warm-up still reaches the solution in about half the steps, with both arms solving 15 of 16.
What it says
A63's caveat is closed: tuning plain XOR's rate moved its mean by 316 steps, against a gap of about 5000. The easy-start speed-up now holds against a tuned baseline for four hard two-input tasks on the GRU -- modular sum, difference, XOR, and a maximum that is hard for plain training -- with ratios from 0.48 to 0.74, and on the LSTM for the sum.
The best plain cell is picked from four on the same seeds the comparison uses, which favours plain, so this selection works against the finding.
What stands
- A67: kill test does not fire. Best plain XOR peak
0.002(interior); mixed minus it-5150.6[-8982.3, -1319.0]steps; ratio0.546.
Limits
- One task at one difficulty; width
48; sixteen seeds. The mixed arm ran at0.003only and was not itself tuned, which if anything understates it.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- baseline
- The thing you compare against. A result without one is not a result.
- GRU
- Gated Recurrent Unit. A compact design for processing sequences one item at a time, with internal switches controlling what it keeps in memory.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- learning rate
- How big a step training takes each time it updates the model. Too small and nothing happens; too big and it never settles.
- LSTM
- Long Short-Term Memory. An older and larger relative of the GRU, also gated, also for sequences.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
- width
- How many internal numbers a model uses at each layer. The usual way we vary model size in these experiments.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.