A Quarter of the Rule Gone
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: Is the task we are studying actually hard? – Often it is not. A rule from 1990 with no parameters beats the trained model on the task most of these results were measured on, and what an intervention costs is set by the task's own structure.
In plain English
What we asked. The easy-start recipe halves the steps when the easy and hard versions of a task share a rule, and slows learning when there is no rule. We broke the rule bit by bit to see how the saving fades.
What we found. It did not fade. With a quarter of the sum's answers replaced by random ones, the whole saving was gone, and with more broken the easy start was slightly slower.
Why it matters. So easier examples help only if they really are the same task. Easy cases that follow a slightly different pattern from the hard ones may give nothing.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU,96training runs of12000steps plus32re-used from A73. The design and the kill test were committed (4a42a25) before any run.
Program v2 Bucket A, item A77. Decisive computation: analysis/sum_eroded.pyanalysis/sum_eroded.json
The question
With symbols and model matched, the easy start takes about half the steps on the sum mod 20 and is slower on random tables (A73, A70). If a rule shared by the easy and hard versions is what the easy start uses, does its lead shrink steadily as the rule is eroded?
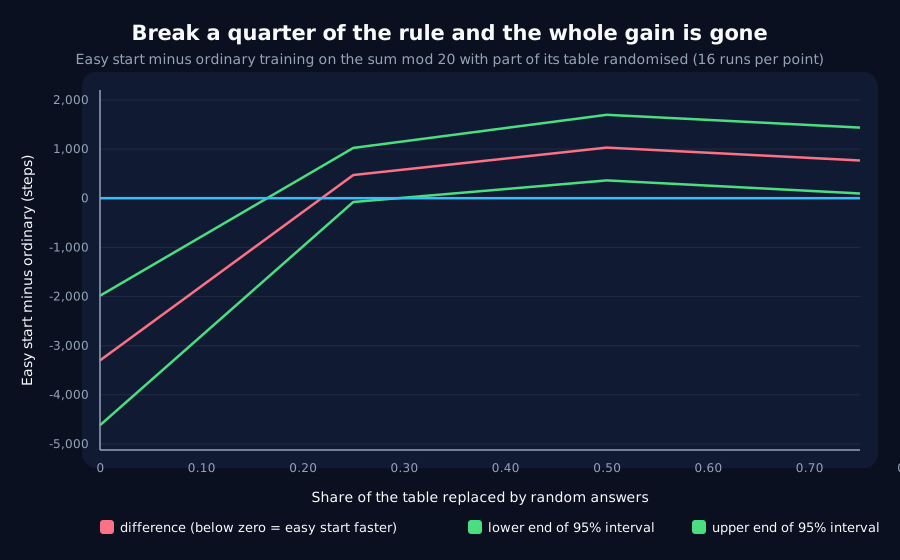
Design: the sum's 20 x 20 table with a fraction p of entries replaced by random symbols (the share actually differing from the sum: 0.228, 0.490, 0.697 at p = 0.25, 0.5, 0.75), the same table for easy and hard lags; A73's seeds and loop, 12000 steps; each arm at its best rate from A73/A75 (mixed 0.005, plain 0.003); p = 0 is A73's cells. Kill test, fixed before execution: Spearman(p, mixed minus plain) across the four rungs below +0.8. Anchor, in code: the p = 0 table reproduces A73's plain run -- held.
Results
p (share randomised) | Plain mean steps | Mixed minus plain (steps) | Solved (mixed / plain) |
|---|---|---|---|
0 (A73) | 6471 | -3300.0 [-4617.4, -1982.6] | 16 / 15 |
0.25 | 5035 | +473.1 [-77.6, +1023.9] | 16 / 16 |
0.5 | 6227 | +1030.0 [+363.1, +1696.9] | 16 / 16 |
0.75 | 7201 | +766.9 [+96.0, +1437.8] | 16 / 16 |
- Spearman
+0.8, at the kill test's boundary (one adjacent pair out of order,0.5and0.75).
The kill test does not fire -- at its boundary. The lead does shrink as the rule is eroded, but not steadily.
What it says
It is a cliff, not a slope. Replacing about a fifth of the table's entries (0.228) removes the whole 3300-step lead; from there to 0.697 the easy start is a little slower, +473 to +1030 steps, much as on a fully random table. Plain training's difficulty barely moves across the rungs (5035-7201), so this is not difficulty. The easy start appears to need the easy versions to share an exact rule with the hard one; a mostly-rule-following table is, to it, a table.
A practical reading: a curriculum built from easier versions of a task helps only if the easier versions really are the same task. Data whose "easy" cases follow a slightly different pattern from the hard ones may get nothing.
What stands
- A77: kill test does not fire (at the boundary,
+0.8). Lead-3300steps atp = 0, gone byp = 0.25(+473), slightly negative top = 0.75.
Limits
- One erosion draw per
p; each arm at one rate (its A73/A75 best), not re-tuned per rung; sixteen seeds; width48. - No rung between
0and0.25, so where in that range the lead disappears is not measured.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- curriculum
- Training on easier examples first and harder ones later, like a school syllabus, rather than on everything at once.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
- slope
- How steeply one quantity changes as another does. A slope of one between a warning and the event it predicts means the warning shifts exactly in step with the event.
- width
- How many internal numbers a model uses at each layer. The usual way we vary model size in these experiments.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.