No Delay at the Edge
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: What decides when a model learns, and can you change it? – Settings dominate, data barely matters, and there is a brief window before the jump in which interrupting the model is unusually costly. Timing can be delayed but not brought forward.
In plain English
What we asked. Grokking, where a model learns the real rule long after memorising its examples, is thought to happen near the smallest amount of data that makes the rule learnable. Our first attempt used far too little data, so this time we searched for that edge.
What we found. We found it: with weight decay, 1,024 examples were enough; without it, 4,096. But every time the model learned the rule, it did so at the same time as it fitted its examples, never long afterwards. We saw no grokking at all. The same weight decay that helped with fewer examples stopped learning altogether with many.
Why it matters. The takeaway: weight decay can cut the data a small model needs to learn a rule, but on this setup it does not produce the famous delayed insight.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU,24training runs of10,000steps. The design and kill test were committed (cd3ff31) before any run.
Program v2 Bucket E, item E10. Decisive computation: analysis/grokking_edge.pyanalysis/grokking_edge.jsonpython analysis/grokking_edge.py (about an hour on a throttled laptop CPU); --reuse re-derives every endpoint.
The question
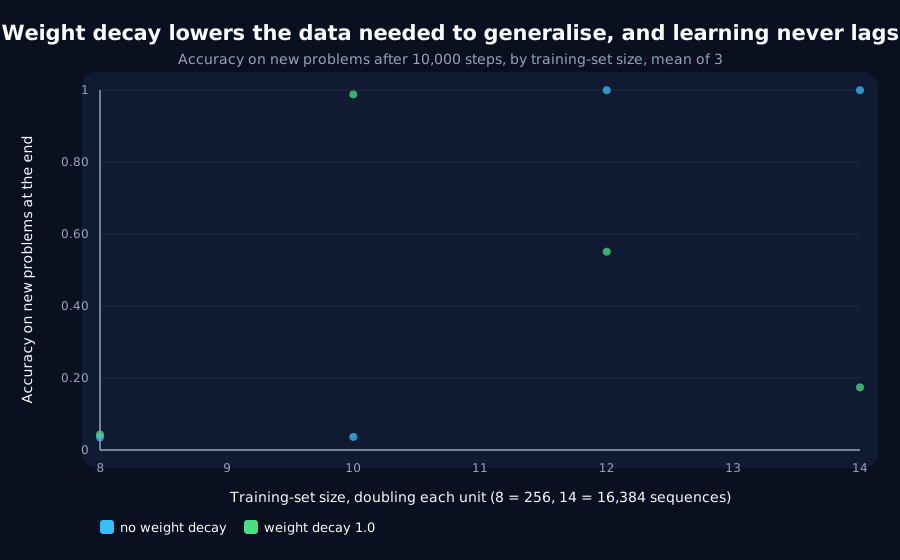
E5 found pools of 8-64 modular-sum sequences are memorised within 100 steps and never generalised; grokking in the literature sits at the edge of data sufficiency, far above those pools. E10 moves up to the edge: pools of 256, 1024, 4096, 16384 sequences, minibatches of 64 drawn from the pool, weight decay 0 and 1.0, three seeds, 10,000 steps, E5's criterion (memorise to 0.99 while held-out is below 0.5, then held-out 0.9 at least three times later).
Kill test, fixed before execution: no cell has two of three seeds that grok.
Result: the kill test fires
| Pool | Weight decay | Memorised (0.99) at | Generalised (0.9) at | Final held-out |
|---|---|---|---|---|
256 | 0 | 550-700 | never | 0.03-0.04 |
256 | 1 | never | never | 0.04 |
1024 | 0 | never | never | 0.04 |
1024 | 1 | 850-1350 | 850-950 | 0.97-1.00 |
4096 | 0 | 1800-5300 | 1400-5150 | 1.00 |
4096 | 1 | never | one seed at 8200 | 0.25-0.98 |
16384 | 0 | 1350-2500 | 1150-1400 | 1.00 |
16384 | 1 | never | never | 0.12-0.21 |
No run groks. Wherever the model generalises, it generalises at or before the step it memorises (ratio 0.6-1.0): training and held-out accuracy rise together, which is ordinary learning.
What the edge looks like
- Weight decay moves the edge down. With decay, three of three seeds generalise from
1024sequences; without it, none do at1024(they cannot even fit the pool in10,000steps), and generalisation needs4096. That is the lever the grokking literature describes -- decay lowers the data a network needs -- here acting without any delay. - The same decay that helps at
1024stops learning at4096and16384(final held-out0.12-0.42on five of six seeds). At1.0on this rig it is strong enough to prevent fitting once the data outgrow what it lets the model hold. - Below the edge the model memorises and stops (
256without decay), as in E5.
What stands
- Kill test fires. Across pools
256-16384, with and without weight decay, no run memorises and later generalises; E5 and E10 together find no grokking on this rig within10,000steps. - Weight decay lowers the data needed to generalise (
1024sequences against4096) and, at the same strength, prevents learning on larger pools. - The bridge to grokking is not made here. The programme's transition and grokking's delayed generalisation remain different phenomena on present evidence.
Limits
- One task, one width, one rate, one decay strength,
10,000steps. Published grokking delays can run to10^5steps; pools between256and1024with decay, run far longer, are where a delay would most likely appear (E11).
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- accuracy
- The fraction of answers a model gets right on questions it was not trained on.
- grokking
- When a network that has memorised its training examples suddenly, much later, learns the general rule and starts getting new examples right.
- held-out
- Data the model was never trained on, kept back specifically to test it. Scoring a model on data it has already seen measures memorisation, not learning.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
- weight decay
- A common training setting that gently pulls a model's internal numbers toward zero, used to stop it over-fitting.
- width
- How many internal numbers a model uses at each layer. The usual way we vary model size in these experiments.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.