Two Papers on Interference
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: What actually happens at the moment a model learns? – It builds machinery rather than selecting it, working through the task in a reproducible order and trying a simpler wrong rule on the way. The visible training curve cannot tell you which is happening.
In plain English
What we asked. We now check recent research every time we decide what to do next. That turned up two 2026 papers about the thing our last few experiments measured: how teaching a model one task gets in the way of others.
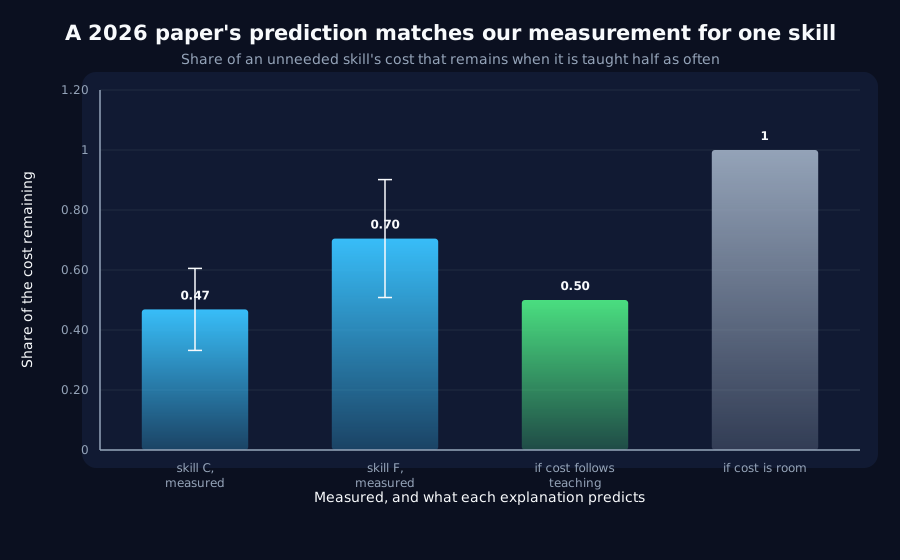
What we found. One paper argues that in ordinary supervised training the interference grows with how much each task is trained. That predicts exactly what we measured for one skill: teach the unneeded task half as often and it costs half as much. The other argues interference shrinks as models get bigger; we only tested two sizes, too close together to tell.
Why it matters. So one outside result now supports ours, and the other gives us a clear next experiment: the same test across much bigger models.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. No training. Two paper abstracts, read against O21's and O24's committed outputs by a committed script.
Program v2 Bucket T, item T1, from the first standing source search (docs/sources.mdanalysis/interference_papers.pyanalysis/interference_papers.jsonpython analysis/interference_papers.py.
The question
The skill-competition thread (O17-O24) found that teaching a small model a skill nothing needs slows the skills it learns afterwards; that doubling the width barely changes the share (O21); and that teaching the unneeded skill half as often removes about half of its cost for one composite (O24). Two 2026 papers bear on exactly this. Only their abstracts were read, as P4 did with its two, and the claims below are theirs as stated there.
- arXiv
2605.29548, "Why Larger Models Learn More: Effects of Capacity, Interference, and Rare-Task Retention" (Huang, Wurgaft, Bansal, Ruis, Saphra, Alvarez-Melis, Lampinen, Potts, Lubana): larger models learn rare and complex tasks because they reduce gradient interference -- common tasks get enough capacity that their gradients weaken and stop overwriting others -- shown on OLMo models from4Mto4Bparameters. - arXiv
2608.03573, "SFT Conflicts, RL Coexists" (Zhu et al.): interference under supervised multi-task training is norm-limited, scaling with the absolute gradient magnitude; under reinforcement learning it is variance-limited and near-orthogonal.
Kill test, fixed before execution: neither paper makes a prediction that O21 or O24 could have contradicted, so the reading adds nothing testable.
Result: the kill test does not fire -- both papers make predictions our runs test
Each claim, in this programme's units, beside the measurement that could contradict it:
| Paper | Prediction here | Measured by | Result |
|---|---|---|---|
2605.29548 | the unneeded skill's share of a composite's time falls as width grows | O21, widths 64 and 128 | falls for F (-0.370 to -0.261); not for C (-0.324, -0.353) or E (-0.277, -0.278) |
2608.03573 | the cost scales with the unneeded skill's gradient contribution: remaining share near the dose | O24, half dose | C 0.469 [0.332, 0.651], containing 0.5; F 0.705 [0.508, 0.889], excluding it |
2608.03573agrees with O24 onC: halving how often the unneeded skill is taught halves what it costs, which is what norm-limited interference predicts under supervised training -- this programme's setting.Fsits between that and pure capacity, with an estimate biased upward (O24's disclosed gate).2605.29548is only weakly borne out at our scale. Its mechanism predicts less interference in larger models, and O21 found almost none between widths64and128. That is not a contradiction: the paper spans three orders of magnitude of parameters and O21 spans a factor of about four. It is a prediction this programme can test further, at a wider range of widths.
What stands
- Kill test does not fire. Both papers make predictions O21 and O24 could have contradicted.
- O24's "competition is pull" agrees with
2608.03573's norm-limited interference forC. - O21's near-constant share at double width is not yet evidence against
2605.29548; the range is too small. - Generates T4: the O20/O21 comparison at widths
256and512, to cover a range where2605.29548's mechanism should show.
Limits
- Abstracts only. P4's lesson was that reading further can change a conclusion; the full texts should be read before either paper is cited as agreement.
- Different scales and tasks: OLMo pretraining and LLM fine-tuning against a width-
64GRU on a planted seven-skill task.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- fine-tuning
- Continuing to train an already-trained model on a new, usually narrower, task.
- gradient
- The direction and amount by which each of a model's internal numbers should change to do slightly better. Training is repeatedly following it.
- GRU
- Gated Recurrent Unit. A compact design for processing sequences one item at a time, with internal switches controlling what it keeps in memory.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- parameters
- The adjustable numbers inside a model. Training is the process of setting them. Model size is usually quoted as a count of these.
- variance
- How spread out a set of numbers is. Rising variance in a signal means it is becoming more erratic.
- width
- How many internal numbers a model uses at each layer. The usual way we vary model size in these experiments.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.